OnPrem World地端世界

Development and custom-AI workstation

OnPrem Branch

A coding assistant for your developers and the place to train your own LLM. Your source code and data never leave the company.

Branches are where new work grows, on trees and in git. The number is the graphics memory in GB.

OnPrem Branch
Illustrative render

For software teams and anyone building their own AI

What it does for your team

Completion in the editorSuggestions as you type in VS Code or JetBrains, through an OpenAI-compatible endpoint.
Ask the codebaseExplain unfamiliar code, find where things happen, write the missing docs.
Coding agentsMulti-file changes, refactors and tests, run by an agent you can review.
Code reviewA second pair of eyes on every pull request, before a human looks.
Your code stays yoursSource code, keys and customer data never reach an outside AI service.
Commercial-use modelsQwen3-Coder models under Apache-2.0, so what they write is yours to ship.
Train your own LLMFine-tune an open model on your documents, terminology, tone and rules: a 32B model on Branch 32, 70B to 120B on Branch 96.

Pick by how you code

Branch 32 for fast completion, chat and mid-size custom models; Branch 96 for coding agents on large codebases and 70B to 120B custom models. The number is the graphics memory in GB.

OnPrem Branch 32
Illustrative render

OnPrem Branch 32

Fast code completion and chat for up to five developers, and room to train a mid-size custom model.

  • ✓ Sized for up to 5 people at the same time.
  • ✓ Runs Qwen3-32B at about 30 tokens a second (estimate)
  • ✓ Coding model Qwen3-Coder-30B-A3B-Instruct at about 193 tokens a second with a 32K context (estimate)
GraphicsNVIDIA RTX PRO 4500 Blackwell, 32 GB (ECC), 200 W
ProcessorIntel Core Ultra 9 285
Memory128 GB DDR5
Storage2 TB NVMe
ChassisHP Z2 G1i tower
Warranty3 years, Ubuntu with an OpenAI-compatible API
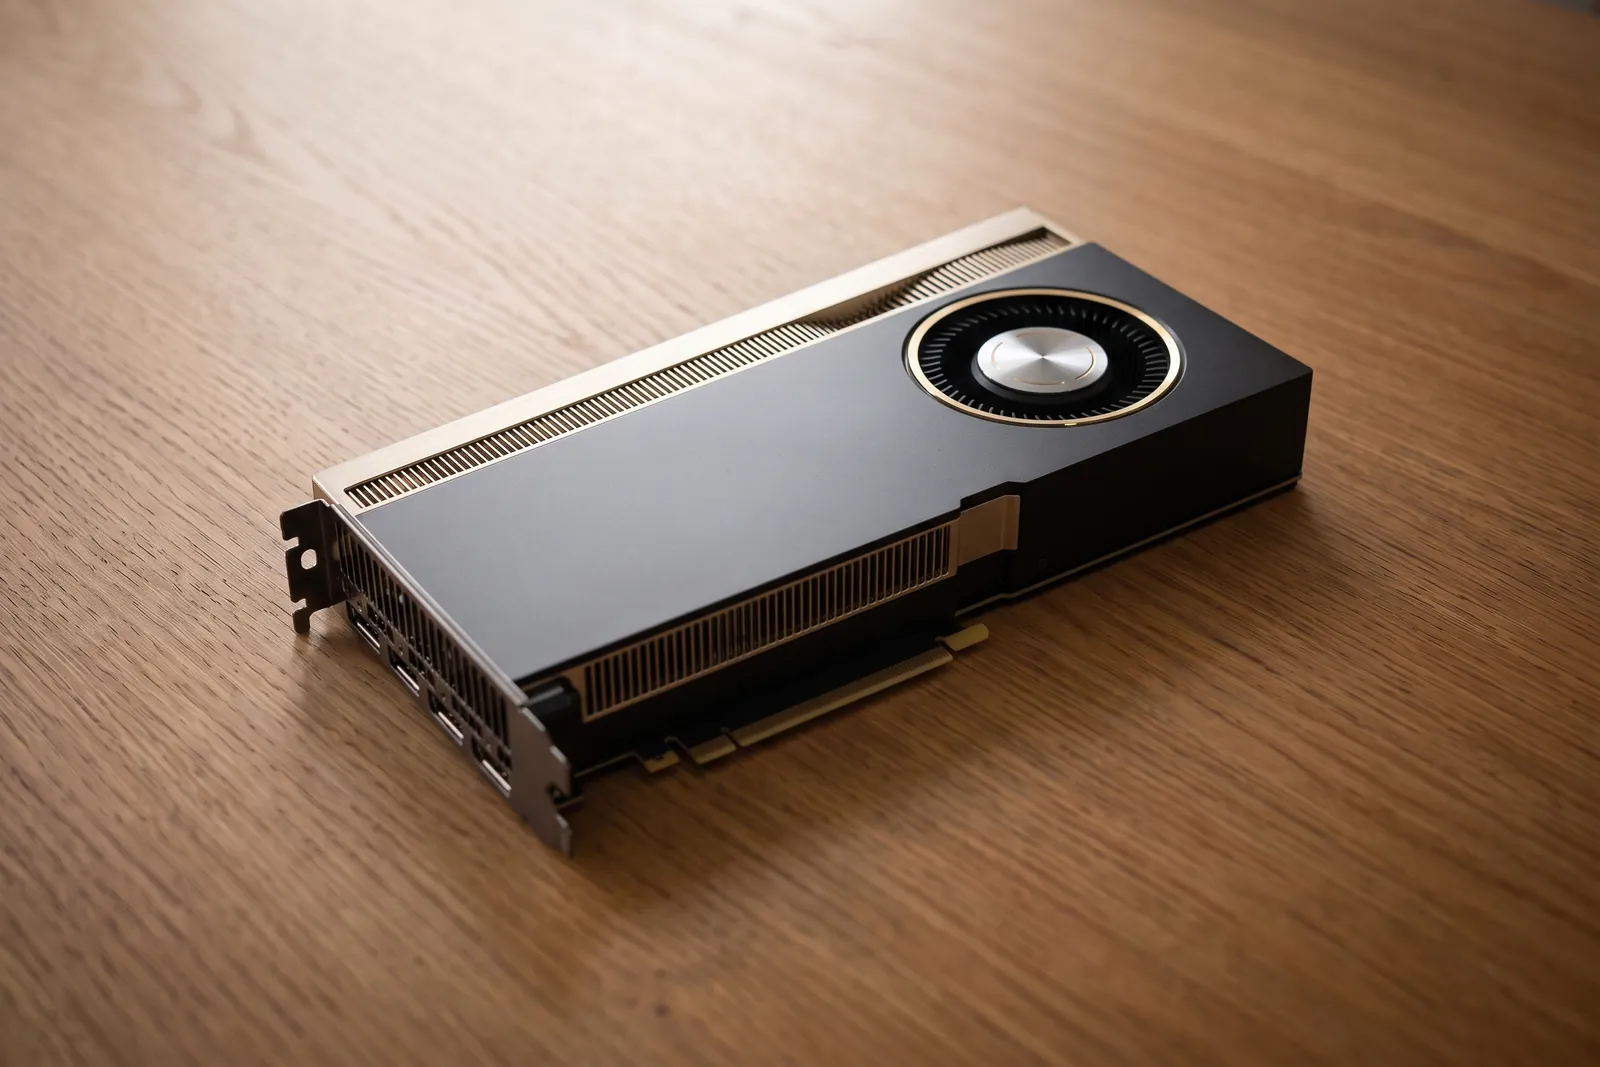
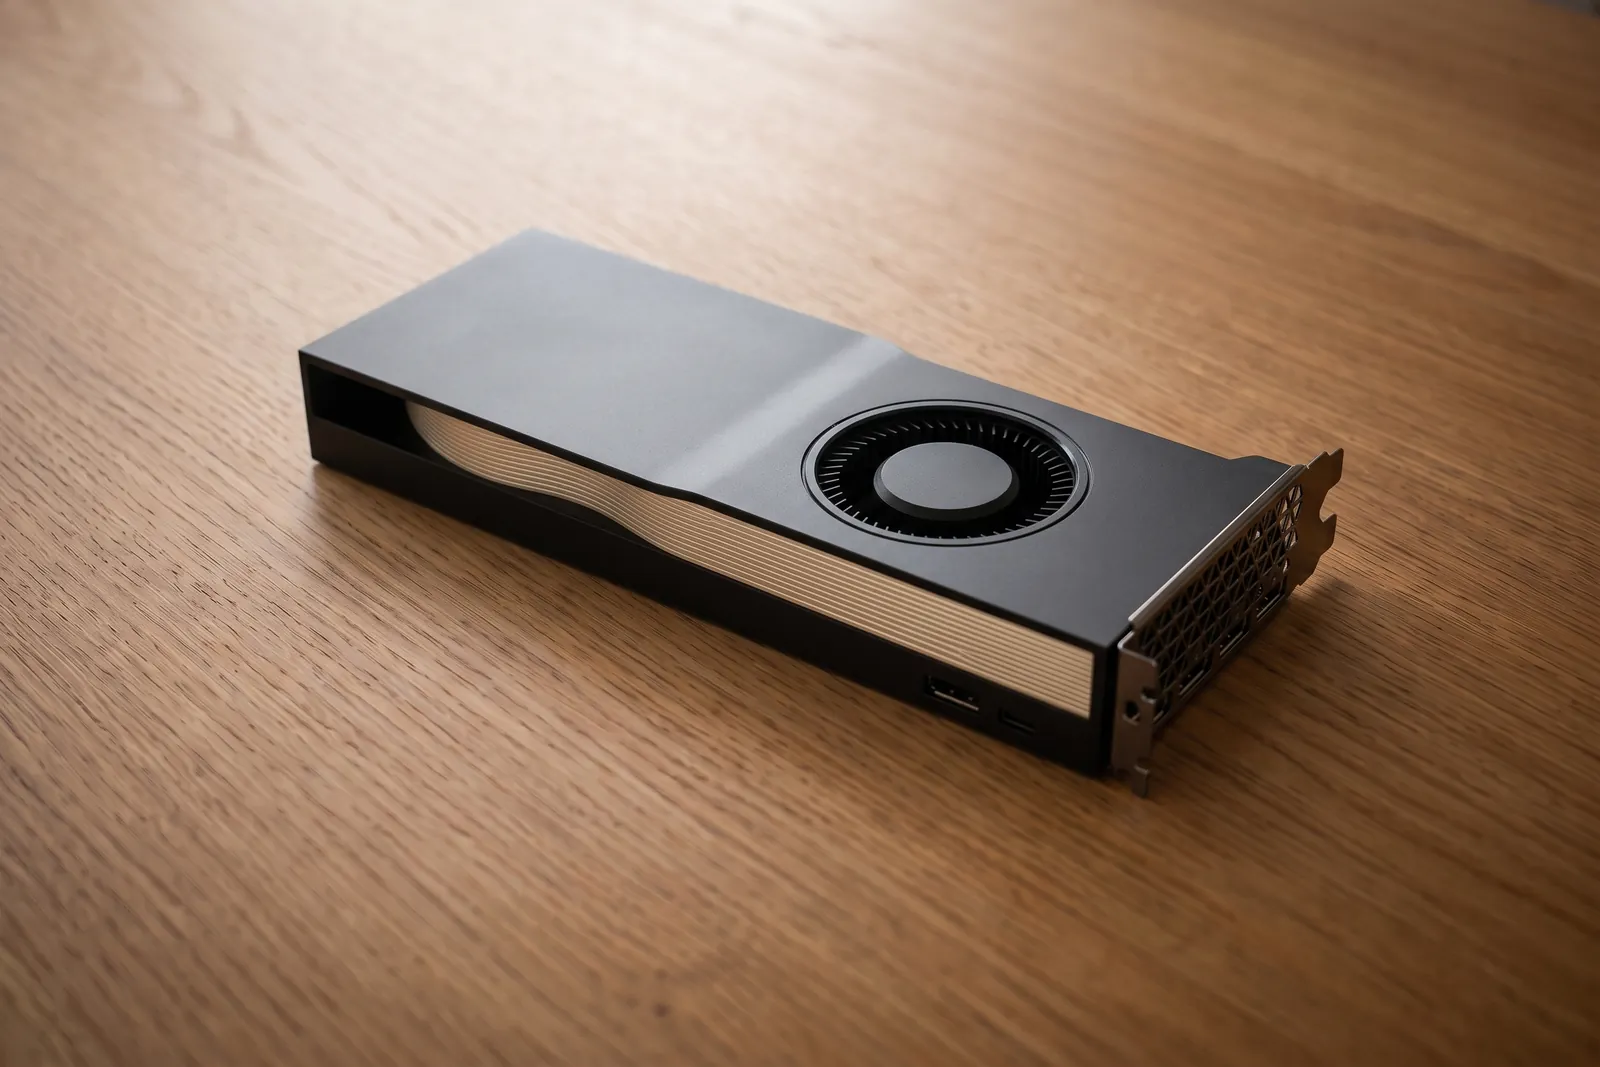
About the graphics card →
OnPrem Branch 96
Illustrative render

OnPrem Branch 96

Coding agents on large codebases for up to twenty developers, and room to train 70B to 120B custom models.

  • ✓ Sized for up to 20 people at the same time.
  • ✓ Runs Qwen3-32B at about 56 tokens a second (estimate)
  • ✓ Also runs the ChatGPT-class gpt-oss-120b
  • ✓ Coding model Qwen3-Coder-30B-A3B-Instruct at about 278 tokens a second with a 32K context (estimate)
  • ✓ Also runs Qwen3-Coder-Next (80B-A3B) for coding agents on large codebases
GraphicsNVIDIA RTX PRO 6000 Blackwell Max-Q, 96 GB (ECC), 300 W
ProcessorIntel Core Ultra 9 285
Memory128 GB DDR5
Storage4 TB NVMe
ChassisHP Z2 G1i tower
Warranty3 years, Ubuntu with an OpenAI-compatible API
About the graphics card →

Prices by quote. We install the software, set it up on site and train your team. Speeds are estimates, not benchmarks.

What we install and set up

Frequently asked questions

Does it work with our editors?

Yes. It serves an OpenAI-compatible API, which VS Code and JetBrains coding plug-ins can connect to. We set them up for your team.

Is our code used to train anything?

No. Everything runs on the machine in your office; nothing is sent out.

Which tier do we need?

Branch 32 for up to five developers doing completion and chat; Branch 96 for up to twenty, or for coding agents on large codebases.

Can we train a model on our own data?

Yes. Fine-tuning a 32B model needs about 26 GB and 70B to 120B needs 41 to 65 GB (Unsloth’s published minimums), so Branch 32 and Branch 96 cover both. We set up the tools and deliver a first model with you.

Can we use the generated code commercially?

The Qwen3-Coder models we install are Apache-2.0 licensed, which allows commercial use.

Not sure? Let Sprout size it for you

Start with Sprout →